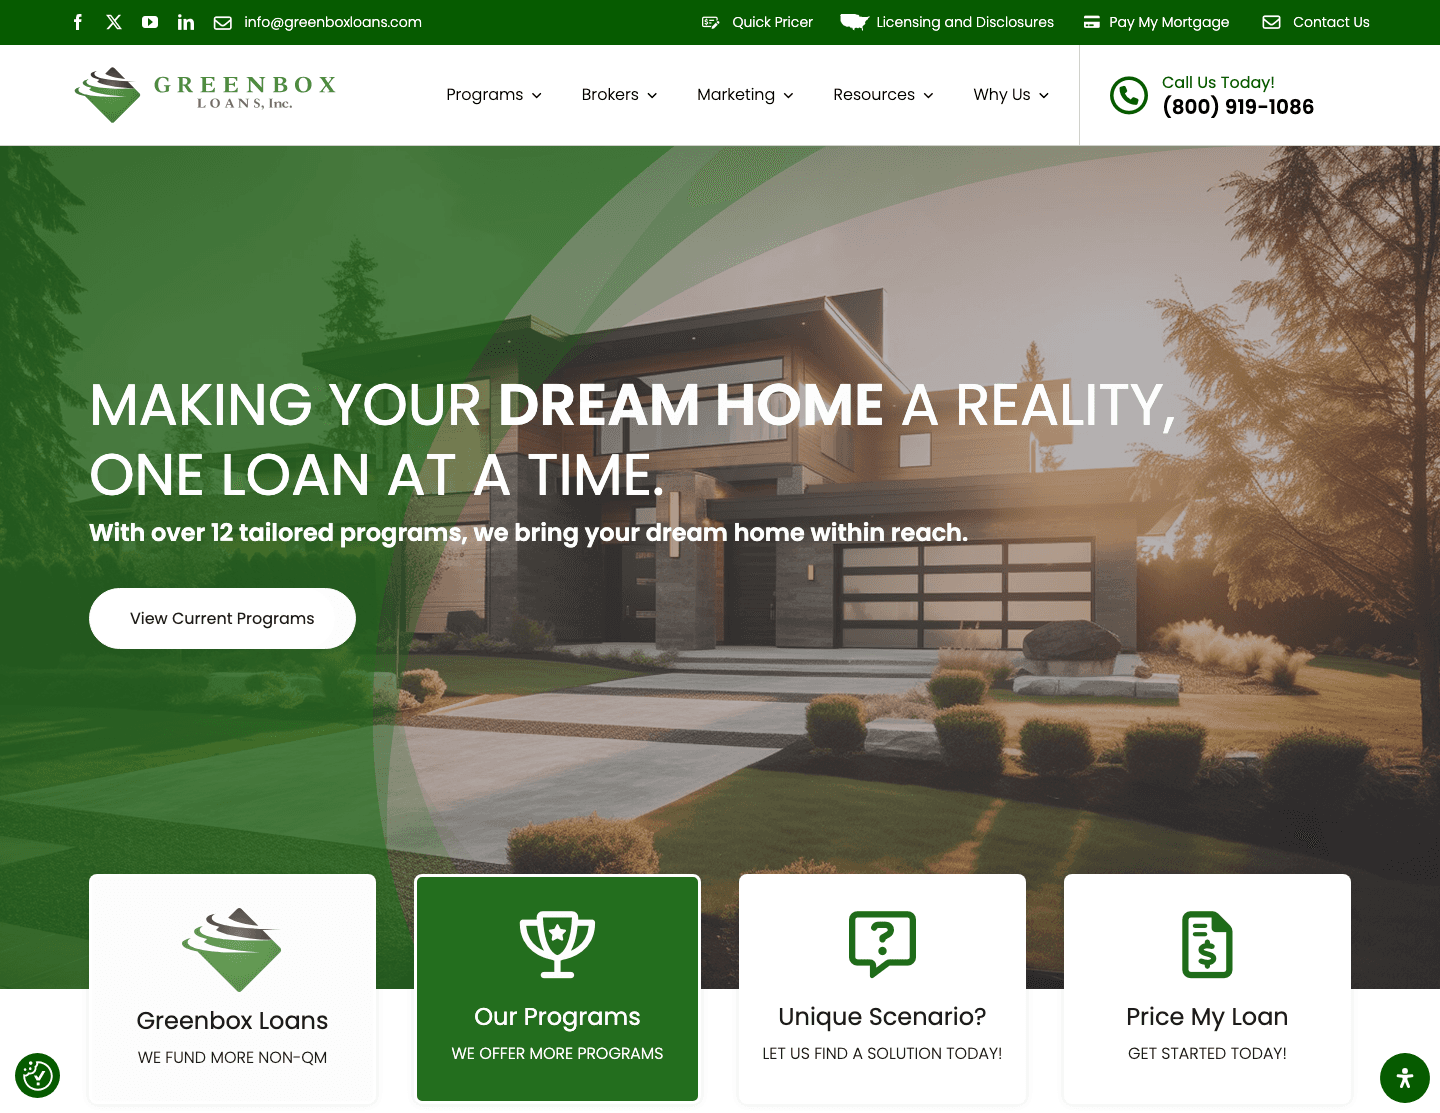
GreenBox Loans
A retrieval-grounded agent over thousands of internal mortgage documents, plus an extraction pipeline that cut a three-day review to under twenty minutes.
- Domain
- Mortgage lending
- Build
- 4-month engagement
- Corpus
- Thousands of indexed documents
- Extraction
- 3 days → 10–20 min
ROI
Project impact
What the work changes.
Critical product knowledge and borrower documents were trapped inside slow, specialist-dependent review.
A grounded knowledge agent and a separate document-extraction pipeline moved both workflows into one controlled operating layer.
Underwriting preparation moves sooner, specialist knowledge becomes reusable, and staff capacity returns to judgment-heavy work.
Context
The brief
Start with the tension, not the treatment.
Mortgage eligibility, pricing, and policy answers lived across thousands of internal product documents. Finding the right one meant knowing it existed first, and the people who knew were the bottleneck.
Separately, reviewing a borrower's bank statements was a three-day manual process. Statements arrived as PDFs across multiple banks and date ranges, and someone had to read every page to classify credits against debits before underwriting could move.
System
The deliverables
What we delivered, layer by layer.
- 01
MIA, a retrieval-grounded conversational agent indexing the full corpus — internal mortgage product documents plus competitor product knowledge — behind a single agentic interface for internal staff.
- 02
Two specialised desks share that corpus: a Greenbox Desk for guideline and policy questions, and a Market Desk for market queries. Per-document scoping keeps an answer inside the sources it should be reading.
- 03
Regenerate, copy, and feedback controls, plus a standing-by status indicator, so a broker can see the agent is grounded rather than guessing — and flag a bad answer in flight.
- 04
A separate agentic OCR and extraction pipeline ingests multiple bank statement PDFs in one upload, merges them across date ranges, classifies credits versus debits, and exposes filters by bank, account, statement range, and description.
- 05
Extractions are named and linked to a client and loan number, so the output feeds downstream underwriting instead of dead-ending in a spreadsheet.
Recorded evidence
Only documented project facts appear here.Bank statement review
- 1,000s
- Documents indexedInternal products + competitor knowledge
- 2
- Specialised desksGuideline policy · market queries
- 4 mo
- Engagement
Outcome
The outcome
- Bank statement review compressed from three days of human work to a 10–20 minute background task.
More selected work
Keep exploring.
 Next case studyHAILOAgentic agency infrastructure
 Daisy+Unified agent platform
 GiftologyGifting platform
 MyAlex.aiAI voice CRM
 Onyx EliteBrand transformation
 AônPremium wellness brand identity
 Legacē HouseFull brand + AI operating system
 EternaGen LabsPeptide research e-commerce
 Gojiberry AIAI sales platform
 Arc By HerAI operations + content automation
 Peptide UAEHigh-trust sales experience
 ProjectSetterVoice Agent + CRM Platform for the trades